“PostgreSQL cache” can mean different things.
If you’re here, you may know already that Postgres doesn’t cache query results. But there’s a whole lot that Postgres does, in fact, cache. The list includes data pages, execution plans, and catalog metadata (not to mention everything that the OS also caches for Postgres).
As a result, the meaning of “PostgreSQL cache” really depends on the context. Sometimes it will mean “keeping data in memory, so that reads avoid disk.” In other contexts, it designates “reusing results, so that repeated queries avoid execution.”
Mixing those two up is why someone might spend a lot of time tuning shared_buffers when they’re trying to fix a CPU problem that has nothing to do with shared_buffers.
This guide is meant to be a helpful first step for anyone trying to get their bearings on the topic of PostgreSQL caching. It’s not comprehensive but it’ll get you started. The goal is to cover:
- what Postgres already does,
- how to figure out which problem you actually have, and
- what your options are when you need a result cache.
In case it’s not obvious, my company builds one of the options for (3). Our solution is not for everyone, but it can be highly beneficial for some production workloads. I did my best to be fair about the tradeoffs.
If you would rather skip ahead and just look at your own workload, our Fit Analyzer reads a pg_stat_statements export in your browser and tells you which of your queries are cacheable, and which ones aren’t. No export handy? The sample report runs itself.
What Postgres already caches for you
shared_buffers for page data
Postgres stores tables and indexes on disk in 8KB pages. Pages that have been recently accessed, however, are kept in a small slice of RAM called shared_buffers. When you access the same data repeatedly, shared_buffers allows Postgres to skip the disk.
The default size for shared_buffers is deliberately tiny, at 128MB (roughly the entire hard drive on my parents’ first IBM desktop). Because it’s so small, “raise shared_buffers” is step one of every tuning guide ever written.
The conventional starting point is 25% of system RAM on a dedicated database server. Changing it requires a restart. Note that if you’re on RDS, Cloud SQL, or any other managed provider, they have already set it to something sensible, so this is advice for servers you run yourself.
Eviction policy for shared_buffers uses a clock-sweep algorithm, an approximation of LRU where each page carries a usage count (capped at 5) that decays as the sweep passes (in other words, pages that keep getting used are kept, the rest are dropped).
A few things to keep in mind with shared_buffers:
-
Big sequential scans won’t flood the cache. A scan over a table larger than a quarter of
shared_buffersruns through a small ring buffer (about 256KB) instead of evicting your hot pages. -
More is not linearly better. Every page also passes through the OS cache, so very large values mostly store the same data twice. It’s usually not worth it to allocate more than 40% of RAM.
-
Reload automatically. pg_prewarm can reload the buffer pool automatically after startup.
The OS provides an additional page cache
Postgres does buffered I/O, so a page that misses shared_buffers is often served from the operating system’s page cache and comes back from RAM anyway.
Your data is effectively cached at two levels, so between shared_buffers and the OS page cache, it’s not unusual that a “disk read” in Postgres statistics doesn’t actually hit the disk.
This is where effective_cache_size trips people up. It doesn’t actually allocate anything, it’s actually a planner hint: an estimate of how much combined caching (shared buffers plus OS) an index scan can expect to benefit from.
Word to the wise:
- Raising
effective_cache_sizedoes not give Postgres more memory! Contrary to what some new users assume.
Plan caching: prepared statements
Parsing and planning cost CPU, and for some short queries it can exceed execution cost.
Postgres will cache plans, but only per session and only when asked. Prepared statements let a connection reuse a plan across executions, and many drivers and ORMs start sending them on their own (but check yours before assuming that’s the case).
For the first five executions Postgres builds a custom plan each time, then compares their average cost against a generic plan and may switch to reusing it. Since version 12, plan_cache_mode lets you force the choice either way.
One challenge is that plans live and die with the connection, which is why most production setups run a pooler, and one of the many reasons to avoid connection churn when possible.
If you want a sense of how much the planner itself has improved over time, we tested ten classic optimizer transformations against Postgres 18.
Catalog caches
Each connection also keeps private caches of table definitions, types, and other catalog data. These caches are known as the relcache and the syscache.
Relcache caches a backend’s parsed relation metadata (columns, indexes, constraints) so Postgres doesn’t re-read pg_class/pg_attribute on every query. Syscache does the same for individual system catalog rows (like a single pg_type or pg_proc lookup). These exist to avoid hammering the catalogs on every planning/execution cycle.
You do not tune these private caches. They explain two common Postgres behaviors:
- Brand-new connections run slower than warm ones, and
- Long-lived connections that touch tens of thousands of relations grow in memory.
Why Postgres has no query cache
MySQL used to ship a built-in query cache that stored the raw result of every SELECT, keyed by query text.
It was deprecated in 5.7 and removed in 8.0. Why? The answer is a lesson in why result caching is hard.
Any write to a table invalidated every cached result touching that table, so under real write load the cache spent its time churning. Every query also had to check the cache first, behind a single mutex, which became a scalability ceiling. Because of these limits, disabling the query cache was a standard MySQL tuning move for years before it was finally retired.
Postgres hackers watched all of that go down and never built a Postgres query cache. The position, restated on the mailing lists whenever the question comes up, is that a shared result cache does not belong in the core execution path. Result caching is the ecosystem’s job.
The wisdom in that decision is seen in the variety of options that the ecosystem has produced: each one picks a different tradeoff between freshness, generality, and how much of the work lands on the developer.
Which layer is actually your problem?
Before you add anything, find out where the time is going. There’s lots of good advice on this out there, and I see a new observability tool come online almost weekly.
Two numbers get you most of the way.
Cache hit ratio tells you whether reads are served from memory:
SELECT sum(blks_hit) * 100.0 / nullif(sum(blks_hit + blks_read), 0) AS cache_hit_pct
FROM pg_stat_database;
For a typical OLTP workload you want 99% or better, but a high hit ratio doesn’t necessarily mean the system is well tuned. You don’t want to hang your hat on a single metric.
Note that blks_read only means “not in shared_buffers,” and many of those reads are satisfied by the OS page cache anyway. Postgres 16 added pg_stat_io for a more accurate picture of real I/O.
To find the tables doing the damage:
SELECT relname, heap_blks_read, heap_blks_hit,
       round(heap_blks_hit * 100.0 / nullif(heap_blks_hit + heap_blks_read, 0), 1) AS hit_pct
FROM pg_statio_user_tables
ORDER BY heap_blks_read DESC
LIMIT 10;
For a single query, EXPLAIN (ANALYZE, BUFFERS) shows the same split per plan node (Buffers: shared hit=4098 read=512). Remember that ANALYZE executes the query for real, so wrap anything other than a plain SELECT in BEGIN ... ROLLBACK.
You can find out where execution time goes using pg_stat_statements. It ships with Postgres but has to be enabled through shared_preload_libraries, which takes a restart. Most managed providers have it on already.
SELECT calls,
       round(total_exec_time::numeric) AS total_ms,
       round(mean_exec_time::numeric, 2) AS mean_ms,
       query
FROM pg_stat_statements
ORDER BY total_exec_time DESC
LIMIT 10;
What you find splits into two cases.
Case one: Your working set does not fit in memory. The symptoms are low hit ratio combined with heavy disk reads. This diagnosis is straightforward but the fix can be tricky. Options include shared_buffers tuning or increasing your RAM, which can be easier said than done. This isn’t the focus of this article, but here’s a helpful guide that I found for the tuning piece, which should get you started.
Case two: Frequency bottleneck. In this case memory is not the bottleneck, frequency is: the symptoms are hit ratio near 100%, CPU pegged, and the top of pg_stat_statements full of fast queries called millions of times.
This one can be missed, because repeated queries will still show up as “cached” in your dashboards. But each of those cached reads still pays for parsing, planning, scanning, visibility checks, and serializing the result. We wrote about that one here: Why Your 99% Cache Hit Ratio Is Still Crushing Your Postgres CPU.
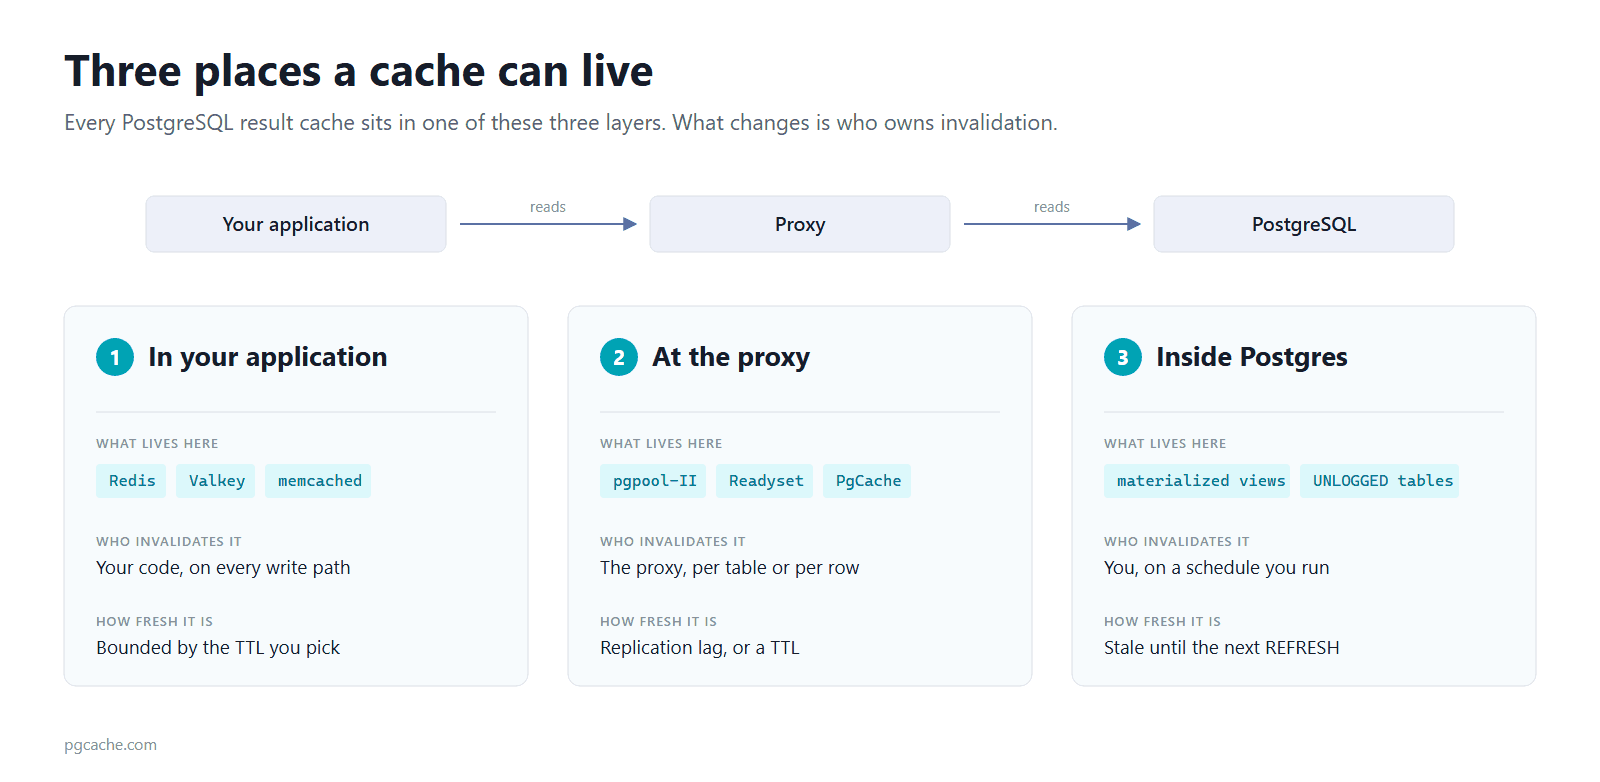
Case two is where result caching and other external mitigations come into play. You have three places to address frequency bottlenecks: inside the database, in your application, or between the two (i.e. a proxy or read replica).
If you already have a pg_stat_statements export in front of you and want the short version of this diagnosis, we built a fit analyzer that reads it and tells you how much of your query time is cacheable. It runs in your browser, so nothing is uploaded.
If a large share of your database time comes back cacheable, then offloading reads is worth doing, whether you do it with PgCache or with one of the other options below. The report ranks your cacheable statements by database time, so you can see exactly which ones you would be taking off the primary.
If it comes back low, that is worth knowing before you build a caching layer you will have to maintain. Look at the reasons it gives you, and look at the write share: if writes dominate your database time, no read cache is going to help you, and neither is a replica.
Caching results inside Postgres
Materialized views
A materialized view precomputes a query and stores the result as an indexable table. This can reduce execution time for complex queries from seconds to milliseconds.
Materialized views shine when a handful of expensive, lag-tolerant queries dominate, because implementing the view requires designing, indexing, refreshing, and monitoring.
Materialization isn’t a cure-all because any change in the inputs requires a rebuild: you run REFRESH MATERIALIZED VIEW and it recomputes everything from scratch. Core Postgres has no native incremental maintenance feature (the pg_ivm extension adds it, with restrictions). A plain refresh blocks readers while it runs, so production setups use REFRESH ... CONCURRENTLY, which requires a unique index.
Using Postgres itself as a cache
Another way of approaching results caching is to use Postgres as the cache: a cache table holding session data or key-value lookups, instead of standing up an external caching layer like Redis (see below). The downside is that cache traffic still lands on your database, which means this approach only works if you have some margin on CPU.
This can carry you further than most people expect. UNLOGGED tables skip write-ahead logging, which makes writes dramatically cheaper. Add an index on the key and a periodic DELETE of expired entries and you have removed an entire service from your stack.
Be aware that the table is truncated after a crash, and it never replicates to standbys. For a cache that is usually fine. It disqualifies UNLOGGED for anything you are not prepared to lose.
Caching results in the application: Redis, Valkey, memcached
Caching results on the application side is the industry default, and is very hard to beat for data that doesn’t change too much. You compute a result, store it in the cache under a key, and check the key before hitting origin next time. When it hits, the cache can return in well under a millisecond without touching the database.
The tradeoff is that you now have a new layer in your stack that requires setup, monitoring, and maintenance: the burden of data correctness has shifted from the database to the added code on the application side.
The easy path is to default to Time To Live (TTL) which periodically flushes cache entries and refills it with correct data from origin. This works well enough, and very well in many cases that have a tolerance for stale data.
Because of the great benefits, it is also not unusual for teams who want better data freshness to set up customized invalidation for the cache. This can bring a number of challenges which have led to the old saying that cache invalidation is one of the two hardest problems in computer science.
-
Invalidation drift. For any code path that writes to Postgres, you have to specify which keys are affected. If you miss one (a migration, a bulk import, an admin tool, a second service on the same database), then your cache will serve stale data.
-
Dual writes. The database write and the cache delete are two operations with no shared transaction. If cache deletion fails, and you miss it, the cache will serve the wrong data.
-
Derived keys. Updating one user invalidates
user:500easily enough. But which cached lists, counts, and aggregates include user 500? Keeping track of dependencies is another challenge for teams implementing caches. -
Stampedes. This is probably the most serious risk, because it doesn’t just affect the validity of the cached data: stampedes can take the database itself down. If a key expires for a very frequent query, then you can get a situation where thousands of concurrent requests miss at once and converge on Postgres to recompute the same result.
Because of the high risks associated with stampedes, there are lots of mitigations (jittered TTLs, request coalescing, soft expiry), but they all require additional planning and code.
The complexity of cache invalidation is why most teams eventually settle on short TTLs. Cap the staleness at 30 seconds and accept it. In many cases, it’s a reasonable compromise.
Caching results at the proxy: pgpool-II
pgpool-II is a connection pooler and load balancer that can also cache SELECT results in shared memory or memcached. That makes it the closest thing in the Postgres world to a MySQL-style query cache, including the bluntness: invalidation is per table, so one UPDATE to one row drops every cached result touching that table.
Another tradeoff is that writes that don’t pass through pgpool are invisible to it. The mitigation in this case is TTL expiry, the same compromise as with key-value stores.
This is workable for read-mostly tables, but it becomes painful under real write traffic. There are cases where TTLs conflict with application requirements about how quickly new inputs are reflected back to the user.
Read replicas: scaling reads without a result cache
When caching is too invasive and the primary is drowning in reads, the classic move is to add a streaming-replication standby. Writes go to the primary, reads go to the copy. This is simple, plain Postgres with no keys or TTLs. Unlike app-side caching that can involve lots of unexpected maintenance, the costs and footprint are in this case fairly predictable.
The simplicity and predictability of read replicas come with their own tradeoffs.
The economics are the primary factor. In the most naive setup, a full replica copies your entire database, which means you’re paying twice for your storage, keeping a full-size instance warm, and paying for data transfer costs (which can be significant at scale).
On most application workloads a fraction of the data serves nearly all the reads. So you are paying to keep the cold majority in two places. We wrote about what a full copy costs separately.
A more involved option that takes advantage of Postgres’ Logical Replication feature-set is to copy only specified tables or queries, but this takes advanced knowledge of the mechanics and doesn’t seem to be as common.
Another tradeoff with read replicas is that they are eventually consistent, like caches. While replication lag is lower than TTL increments, it is still lag, making it a blocker for systems with very high consistency requirements.
CDC-driven caching: invalidation as a data problem
Every result cache above struggles with the same question. When is a cached result no longer true? Application-side caches use gross estimates in the form of TTLs. Operators schedule refreshes on materialized views. And pgpool drops whole tables in the event of a write.
The invalidation problem and its workarounds have been accepted as an unavoidable part of scaling reads on Postgres.
But between the complicated logic of key-value stores and the all-or-nothing costs of read replicas, there is a third path: CDC-driven caching. For the better part of a decade, Postgres has been producing the exact data that is needed to defuse the cache invalidation quandary: the Logical Replication stream, which is a precise, ordered feed of every row-level change.
A cache that subscribes to the Logical Replication stream does not have to guess. It gets told what changed, and it can update or drop exactly the entries that depended on the changed rows, within typical replication lag.
That is the design behind CDC-driven caches. It was also my co-founder James’s hunch 5-6 years ago. Turns out, it was a good one.
Two approaches: declared and drop-in
At present, I know of two projects that are building CDC-driven caches: the first is Readyset, and the second is our company PgCache. Both watch the replication stream, but we take different approaches to deciding which queries get cached.
Readyset sits between origin and application and is wire-compatible with both MySQL and PostgreSQL. It maintains its cached results with an incremental view maintenance engine, filling on demand rather than materializing whole result sets, which delivers the sub-millisecond response times that suit read-heavy workloads and applications seeing high CPU utilization. Those caches are declared: you run CREATE CACHE for each query you want accelerated, and anything you have not declared is proxied to the upstream database. Sizing is the other thing you need to plan for, since Readyset runs against a memory budget. How much you need depends on your table sizes, query complexity, and data distribution.
PgCache is drop-in. There is nothing to declare: live traffic decides what gets cached, and the replication stream keeps the data fresh row by row, and invalidates when necessary. We built it to be a lightweight, PostgreSQL-native addition to a scaling database stack.
Both are bound by replication lag, so both are eventually consistent, which makes either one a poor fit for queries that demand absolute, real-time accuracy.
PgCache: A “Smart Read Replica”
PgCache is the solution we’re building. It sits at the same point in the stack as pgpool’s cache, as a proxy between the app and Postgres. In contrast to pgpool, PgCache carries out invalidation at the row-level, instead of at the table-level. Cacheable SELECTs are served from the cache. Everything else passes through to your database unchanged, with no cache keys or invalidation code in your application.
Because the cache fills from live query traffic and holds only what actually gets read, it ends up shaped like a replica of your traffic rather than a copy of your whole database. That is why we call it a smart read replica.
PgCache provides benefits at several levels:
-
For teams considering read replicas or already running multiple copies, it can reduce the infrastructure footprint and cost.
-
For teams seeking to offload reads but unsure if it warrants the overhead of a new key value store, PgCache offers a drop-in layer that automatically and natively caches many query shapes.
As with the other solutions described above, there are a number of tradeoffs.
Unlike a key value store with manually built (and customizable) cache logic, PgCache automatically handles a fixed set of query shapes, and passes through shapes it cannot parse to origin. Pass-through shapes currently include non-immutable functions (now(), random()) outside the SELECT list, LATERAL subqueries, and Recursive CTEs.
PgCache does not yet support Row Level Security. If your reads depend on RLS policies, PgCache isn’t a fit for you today; support is on our roadmap for this fall (Q4).
Transactions are a different case. They work, but nothing inside one is served from cache: every query in a transaction is forwarded to your origin, so a session always reads its own writes. Outside a transaction, typical replication lag applies. A stronger read-after-write guarantee is also on the Q4 roadmap.
Finally, as a client of the Logical Replication stream, PgCache inherits the well-known caveats common to all read replicas: (i) consistency is bound to the Logical Replication stream; (ii) dropped tables can be missed in certain edge cases; and (iii) there are risks of WAL accumulation if the replication slot becomes unattended.
Matching the layer to the symptom
| Symptom | Reach for |
|---|---|
| Hit ratio below ~99%, heavy disk reads | RAM and shared_buffers first |
| Hit ratio fine, CPU pegged by repeated reads | A result cache (rows below) |
| A few expensive aggregates, staleness tolerated | Materialized view |
| Distinct hot queries, team can own invalidation | Redis / Valkey |
| Many distinct hot queries, nobody wants to own invalidation | PgCache / Readyset |
| Reads must scale and a result cache is not an option | Read replica |
| Writes are the bottleneck | None of these. Caching does not help writes |
When caching is the wrong answer
Skip this whole exercise when:
-
The database fits in RAM and the CPU is bored. A well-tuned single instance goes much further than the architecture diagrams suggest. Every time you add a cache you add complexity and failure modes. Do not add extra layers before you need them.
-
Queries rarely repeat. Caching pays when the same question gets asked again. Workloads dominated by unique queries (ad-hoc analytics, search) get very little from any result cache. (The exception is PgCache, which can serve new queries from cache if/when the cache already holds the rows needed to answer the query, a feature we call covered queries or subsumption. For example, if the cache holds
SELECT ... WHERE country = 'USA', it can serveSELECT ... WHERE country = 'USA' AND state = 'DE'.) -
The table is write-hot. Entries get invalidated as fast as they fill. You get all the overhead of a cache and almost none of the hits.
-
Missing an update is unacceptable. Some reads, like a balance check before a withdrawal or inventory before a sale, should just hit the primary. Every cache in this guide, replicas included, is eventually consistent somewhere. Route those queries around whatever you deploy.
Finally, make sure you exhaust the boring fixes first. An EXPLAIN ANALYZE session that ends in a new index (built CONCURRENTLY, so you do not lock writes on a big table) is going to be cheaper and easier than any of the solutions described on this page.
Common questions
Does PostgreSQL have a built-in query cache?
No, by design. MySQL removed its query cache after it became a scalability bottleneck, and Postgres never built one. Postgres caches data pages (shared_buffers), execution plans (prepared statements), and catalog metadata. Result caching comes from the ecosystem: materialized views, pgpool-II, application-side caches, or CDC-driven caches.
What is a good Postgres cache hit ratio?
99% or better for OLTP-style workloads. But a high hit ratio only tells you reads are coming from memory. It does not tell you your queries are cheap. If the hit ratio is fine and the CPU is still high, you have a result-caching problem.
Is effective_cache_size the same as shared_buffers?
No. shared_buffers allocates memory. effective_cache_size tells the Postgres query planner how much total caching (Postgres plus OS) to assume when it is choosing plans.
How is a CDC-driven cache different from Redis?
With Redis, logic at the application level decides what to cache and when each entry goes stale. A CDC-driven cache automates both. It fills from live query traffic and subscribes to the Postgres replication stream, so a change on the primary updates or invalidates the affected entries with no application code.
How to get started with PgCache
Our conviction is that a majority of the read replicas and key value stores currently being used to optimize reads for Postgres databases are a waste of resources. It shouldn’t be so complicated or costly to scale Postgres, and we built PgCache to inspire better production architectures.
If your diagnosis of your database’s bottleneck says something like “the CPU is doing the same read work over and over,” that is what PgCache is made to fix. We’ve tried to make it as easy as possible: it’s a proxy that you point your connection string at. It requires no application changes and works with PostgreSQL 16, 17, and 18. PgCache speaks the wire protocol so the deployment model is “if it’s Postgres, it just works.”
The how caching works page documents what gets cached and what passes through, pattern by pattern. There is a free tier on AWS Marketplace and a Docker image.
James also published the benchmark harness he uses to test PgCache, so you can run the comparison yourself rather than taking our numbers on faith. Point it at something close to your real workload.
If you only have 5 minutes, the easiest way to evaluate PgCache is to use our in-browser fit analyzer that will tell you what can be cached, in terms of queries and database time. Just drop in a pg_stat_statements report and click “analyze” (it runs locally so you’re not disclosing any information).
This guide is based on more than a year of conversations with DBAs, SREs, and Postgres folks all over the world. Those conversations have been my favorite part of building PgCache. If you have any questions or additions, please write me at [email protected].